

Service time and downtime are two foundational metrics that determine how reliably any system, application, or server delivers value to its users. In simple terms, service time refers to the agreed period during which a system is expected to be fully operational, while downtime is any moment within that window when the system becomes unavailable — whether due to a scheduled maintenance window or an unexpected failure. Understanding what is “typical” for these metrics is not a luxury for IT teams; it is the baseline for building trustworthy, contractually sound, and operationally resilient services.
Industry benchmarks for uptime are most commonly expressed through the “nines” system — 99.9%, 99.99%, and 99.999% — each representing a progressively tighter ceiling on acceptable downtime. A service running at 99.9% uptime, often called “three nines,” is still permitted nearly nine hours of downtime per year under its SLA. By contrast, “five nines” (99.999%) allows only around five minutes of annual downtime, a standard reserved for mission-critical infrastructure in finance, healthcare, and enterprise cloud platforms. Knowing which tier applies to your service is the starting point for every availability conversation.
Calculating service time and downtime accurately requires more than a surface-level formula. The standard calculation — subtracting total downtime from agreed service time and expressing the result as a percentage — sounds simple, but the variables beneath it are not. Planned maintenance, unconfirmed monitoring errors, and paused monitoring periods all affect the final number, which means organizations relying on raw uptime percentages alone often report figures that do not honestly reflect the experience of their users.
Beyond benchmarks and calculations, the real challenge is minimizing downtime before it occurs and recovering from it faster when it does. Hardware failures, misconfigured software, and external cyberattacks are among the most common causes of unplanned outages, and each requires a different mitigation strategy. Next, this article walks through every dimension of service time and downtime — from foundational definitions to advanced recovery metrics — so that engineers, IT managers, and business owners can make informed decisions about their availability standards.
What Are Service Time and Downtime?
Service time is the contractually or operationally defined window during which a system must be available, and downtime is any period within that window when the system fails to meet that obligation — whether through a planned outage or an unexpected failure.
To better understand these two concepts, it helps to examine not just their definitions in isolation but how they interact with each other and with the broader framework of availability management.
Service time, often referred to as Agreed Service Time (AST), is the foundation on which all availability calculations rest. It is the total number of hours or minutes during which a service provider has committed to keeping a system operational. This could be 24/7 for a cloud hosting provider, or only during business hours for an internal IT helpdesk system. The distinction matters enormously: a system that goes offline at 2 a.m. on a Sunday behaves very differently under an SLA depending on whether that hour falls inside or outside the agreed service window.
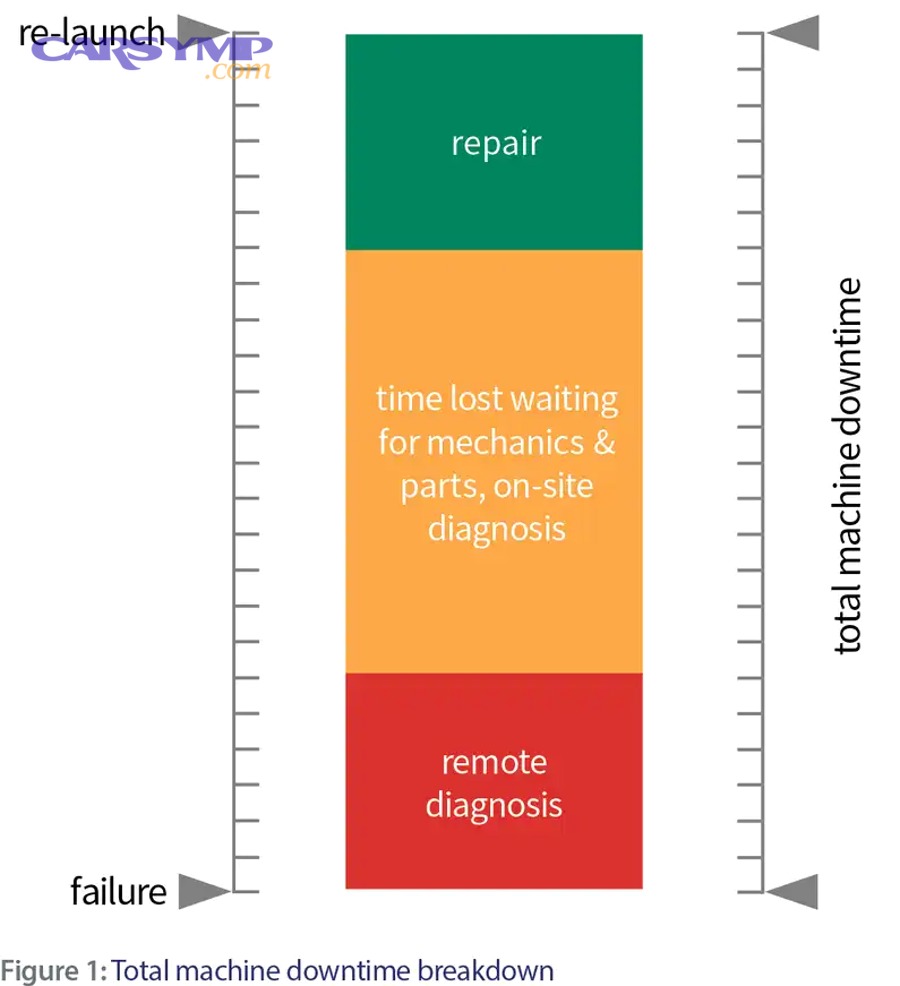
Downtime, by contrast, is the inverse — the measurable gap between what was promised and what was delivered. It encompasses both planned downtime, such as scheduled maintenance or software upgrades, and unplanned downtime, such as crashes, hardware failures, and cyberattacks. While the term is most commonly applied to IT and server environments, downtime also applies in manufacturing (production line stoppages) and even workforce management (employees blocked from working due to system unavailability). A common misconception conflates downtime simply with a server being “off.” In reality, a server can be technically running while still delivering downtime from the user’s perspective — for example, when a critical service process has crashed but the host machine remains online.
What Is the Difference Between Planned and Unplanned Downtime?
Planned and unplanned downtime differ in origin and impact: planned downtime is a controlled, pre-announced interruption scheduled by the service owner, while unplanned downtime is an unexpected failure that occurs without warning.
Specifically, planned downtime is used to perform tasks that cannot be executed while the system is live — deferred hardware repairs, OS patching, database migrations, or configuration updates. These events are typically scheduled during low-traffic windows (often called “maintenance windows”) to minimize disruption. Because they are communicated in advance, users can prepare, and organizations can exclude planned downtime from certain SLA calculations depending on contract terms.
Unplanned downtime, on the other hand, is the type that damages reputation and revenue. It stems from hardware malfunctions, software bugs, misconfiguration errors (the single most common cause of IT outages), security incidents, and third-party dependency failures. Unplanned outages carry an unpredictability that makes them costlier to recover from — not just financially, but in terms of customer trust.
The distinction between the two carries real financial weight. According to a 2019 report by Veeam, organizations experience unplanned downtime on average 5 to 10 times per year, with the average cost of a single hour of unplanned downtime reaching $102,450.
What Is the Difference Between Uptime and Availability?
Uptime and availability are related but distinct metrics: uptime measures the raw percentage of time a system is running, while availability measures the proportion of time a system is both operational and accessible — factoring in planned maintenance periods.
This distinction is often called the “uptime myth.” A system can report 100% uptime — meaning it never crashed — and still have poor availability if it was taken offline repeatedly for scheduled maintenance during peak hours. Conversely, a system with a brief unplanned outage may still meet its availability SLA if the maintenance window exclusions are applied correctly.
A useful analogy comes from manufacturing: uptime is comparable to OEE (Overall Equipment Effectiveness), which measures whether a machine is running, while availability mirrors TEEP (Total Effective Equipment Performance), which measures whether the machine is delivering value during all available time. For IT teams and managed service providers, tracking both metrics separately — and reporting them honestly — is what separates transparent SLA management from what is sometimes called the “watermelon effect”: green on the outside, red on the inside.
What Are the Typical Benchmarks for Service Time and Downtime?
There are five widely recognized uptime tiers used as industry benchmarks for service time and downtime, ranging from 99% to 99.999%, each representing a different threshold of acceptable unavailability based on service criticality.
These tiers, commonly referred to as the “nines” system, give IT teams, vendors, and customers a shared language for expressing reliability expectations. Understanding where your service sits within this framework — and what that means in terms of real time lost — is essential before drafting any SLA or evaluating a vendor’s reliability claims.
What Do the “Nines” of Uptime Mean in Practice?
The “nines” of uptime translate abstract percentages into concrete time windows that make availability commitments immediately actionable and comparable.
The following table summarizes exactly how much downtime each uptime tier permits across different time frames. This context is critical when evaluating SLA terms, because a 0.1% difference in percentage can mean the difference between 8 hours and 52 minutes of annual downtime.
| Uptime Tier | Annual Downtime | Monthly Downtime | Daily Downtime | Typical Use Case |
|---|---|---|---|---|
| 99% (Two Nines) | ~3.65 days | ~7.2 hours | ~14.4 minutes | Internal tools, low-priority systems |
| 99.9% (Three Nines) | ~8.76 hours | ~43.8 minutes | ~1.44 minutes | Standard SaaS platforms, web hosting |
| 99.99% (Four Nines) | ~52.6 minutes | ~4.38 minutes | ~8.64 seconds | Business-critical applications |
| 99.999% (Five Nines) | ~5.26 minutes | ~26.3 seconds | ~0.86 seconds | Finance, healthcare, enterprise cloud |
Five nines (99.999%) has become the gold standard for mission-critical services precisely because it limits annual downtime to under six minutes. Achieving this level requires significant infrastructure investment — redundant systems, automatic failover, real-time monitoring, and near-instant incident response — which is why it is typically reserved for services where every second of unavailability has measurable financial or safety consequences. For most standard SaaS products and web services, three nines (99.9%) represents the practical baseline, while four nines is increasingly expected for any platform handling financial transactions or regulated data.
What Is a Typical Service Time Window for Different Industries?
Typical service time expectations vary by industry, with e-commerce and finance demanding the highest uptime and internal IT operations often tolerating lower thresholds.
More specifically, industry context shapes not just the SLA percentage but the consequences attached to missing it. In e-commerce, a two-hour outage during a peak shopping period can generate revenue losses that dwarf the cost of the infrastructure needed to prevent it. In contrast, an internal HR portal going offline for two hours on a Tuesday morning may cause inconvenience but carries little financial consequence.
- E-commerce: Near-zero tolerance for downtime; even brief outages during high-traffic events (sales, launches) cause measurable lost revenue and customer churn.
- Banking and Finance: Regulatory requirements in many jurisdictions mandate high availability; outages can trigger compliance violations in addition to financial losses.
- SaaS platforms: Typically target 99.9% to 99.99% depending on their customer segment; enterprise-tier customers almost always demand four nines or higher.
- Healthcare: Uptime is a patient safety issue — electronic health record systems, diagnostic tools, and communication platforms must remain available to support clinical decisions.
- Internal IT systems: May operate on narrower service windows (e.g., business hours only), which changes how availability is calculated and what constitutes a breach.
How Do You Calculate Service Time and Downtime?
Service availability is calculated using a three-variable formula — Agreed Service Time, actual downtime, and total monitored time — which together produce the uptime percentage that determines whether an SLA has been met.

The formula looks simple on the surface, but the quality of the inputs determines the accuracy of the result. Organizations that track downtime manually, inconsistently exclude planned maintenance, or fail to account for monitoring tool behavior often end up with availability figures that are technically computed but operationally misleading.
What Is the Formula for Calculating Service Availability?
The standard formula for service availability is: Availability (%) = (AST − Downtime) / AST × 100, where AST is the Agreed Service Time and downtime is the total duration of all outages within that window.
To illustrate with a concrete example: if a service has an Agreed Service Time of 100 hours and experiences 2 hours of downtime, the availability is (100 − 2) / 100 × 100 = 98%. Conversely, downtime percentage is calculated as Downtime / Total Time × 100, and uptime percentage as 100% minus the downtime percentage.
One critical nuance is how planned downtime is treated. Depending on the SLA terms, scheduled maintenance windows may be subtracted from the total AST before calculating availability — meaning a planned 4-hour upgrade window doesn’t count against the vendor’s availability commitment. When this exclusion is not clearly defined in the contract, disputes arise between service providers who claim they met their SLA and customers who experienced unavailability regardless of the reason. This is why SLA language around planned maintenance exclusions deserves as much attention as the uptime percentage itself.
What Factors Affect Uptime and Downtime Calculations?
At least five factors beyond raw outage time affect the accuracy of uptime and downtime calculations, including monitoring pause periods, error confirmation logic, and performance-based thresholds.
Specifically, modern monitoring tools introduce several layers of nuance that raw formulas do not capture:
- Monitor pause periods: When a monitor is paused (e.g., during a known maintenance window), most tools record this time as “unknown” rather than downtime. In the standard formula, unknown time is typically counted as uptime: (uptime + unknown) / (uptime + downtime + unknown). This can inflate reported uptime figures.
- Confirmed vs. unconfirmed errors: Reputable monitoring platforms perform a double-check from a second checkpoint before marking an error as confirmed downtime. The time between an unconfirmed and confirmed error is typically treated as uptime, which means brief connectivity blips may not register as official downtime.
- Performance-based error conditions: If a monitor is configured to trigger an error when response time exceeds a threshold (e.g., page load over 3 seconds), the system may report downtime even when the server is technically available. This is intentional — slow availability is often worse than no availability from the user’s perspective.
- Concurrent monitoring: Standard monitoring tools use double-check logic; concurrent monitoring tools do not, which changes how errors are counted and how quickly downtime is registered.
- Third-party dependencies: CDN failures, DNS outages, or external API failures can cause user-facing downtime even when the origin server is fully operational, complicating attribution in SLA disputes.
What Are the Most Common Causes of Downtime?
There are four primary categories of downtime causes: hardware failures, software and configuration issues, security incidents, and external dependency failures — each requiring a distinct mitigation strategy.
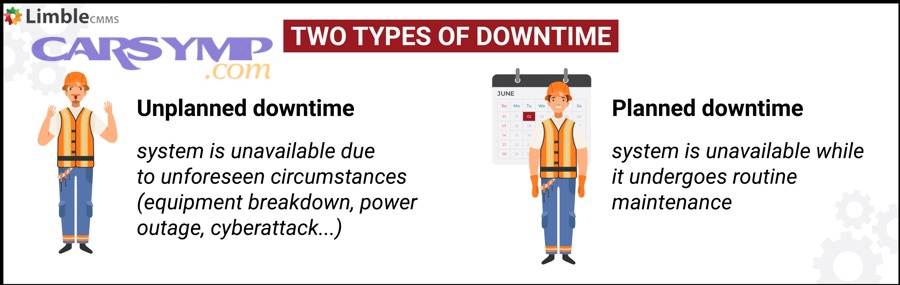
Understanding the root cause of downtime is not merely an academic exercise. The right prevention strategy depends entirely on which category of failure is most prevalent in a given environment. An organization suffering repeated hardware failures needs a different response than one whose outages are driven by misconfigured deployments.
What Hardware and Software Issues Cause Unplanned Downtime?
Hardware failures and software defects are the two most common technical triggers of unplanned downtime, each capable of taking an entire service offline within seconds.
On the hardware side, the most frequent culprits include:
- Storage failures: Hard drive and SSD failures remain a leading cause of server outages, particularly in aging infrastructure.
- Power supply failures: A failing PSU can take an entire physical server offline with no warning.
- Memory (RAM) errors: Faulty memory modules can cause intermittent crashes that are difficult to diagnose before they escalate into full outages.
- Network equipment failures: Switch, router, or NIC failures can isolate servers from users even when the servers themselves are fully functional.
On the software side, bugs in application code, failed deployments, and outdated dependencies introduce instability that can cause cascading failures. The CrowdStrike incident of July 2024 — in which a faulty device driver update caused approximately 8.5 million Windows machines worldwide to crash and enter a boot loop — stands as the largest IT outage in recorded history, demonstrating how a single software update, when not properly staged and tested, can trigger global service disruptions affecting critical infrastructure including 911 emergency services.
Is Human Error a Leading Cause of Service Downtime?
Yes, human error — particularly misconfiguration — is consistently cited as one of the top causes of IT downtime, responsible for a significant share of unplanned outages across organizations of all sizes.
Specifically, misconfiguration occurs when a planned change to a system’s configuration is applied incorrectly — whether due to manual error, insufficient testing, or inadequate change management processes. Unlike hardware failures, which are often sudden and obvious, misconfiguration-related outages can be slow to diagnose because the system appears to be running while silently failing in specific areas.
The risk is compounded by how most organizations manage configuration backups: manually, by skilled engineers who must track changes across multi-vendor environments with limited tooling. Automation solutions exist to manage configuration backups, but very few cover configuration recovery — the step that actually determines how long the outage lasts once a misconfiguration is identified.
According to a 2019 Veeam Cloud Data Management Report, organizations encounter unplanned downtime on average 5 to 10 times per year, with the average cost of one hour of downtime reaching $102,450 — a figure that underscores why preventing human-error-driven outages delivers strong financial return on investment.
How Can You Minimize and Manage Service Downtime?
Service downtime can be minimized through a combination of infrastructure redundancy, automated monitoring, disciplined change management, and incident response planning — together targeting both the frequency and duration of outages.
These two dimensions — frequency and duration — are equally important. A strategy that reduces outage frequency but does nothing to accelerate recovery will still produce poor availability if the outages that do occur last for hours. Effective downtime management addresses both simultaneously.
What Best Practices Reduce Unplanned Downtime?
The most effective practices for reducing unplanned downtime combine proactive infrastructure design with disciplined operational processes, targeting the most common failure points before they escalate into outages.
- Infrastructure redundancy: Deploying failover systems, redundant power supplies, and load-balanced servers ensures that no single component failure takes the entire service offline. This is the architectural foundation of high-availability systems.
- Automated configuration backup and recovery: Replacing manual configuration management with automated tools eliminates the human error risk associated with configuration changes and dramatically reduces recovery time when misconfigurations occur.
- Regular patching and update schedules: Keeping operating systems, applications, and firmware current closes known vulnerability windows and reduces the risk of software-driven failures. Patching should be staged — tested in a lower environment before production deployment.
- Incident response runbooks: Pre-written response procedures for common failure scenarios allow on-call engineers to act immediately without waiting for escalation or diagnosis, directly improving MTTR.
- Capacity planning: Many outages are triggered not by failure but by demand spikes that exceed system capacity. Proactive scaling — whether vertical, horizontal, or through auto-scaling in cloud environments — prevents performance degradation from crossing into outage territory.
For organizations evaluating external service providers, it is worth knowing How to evaluate quotes for timing belt service and other maintenance contracts: the pricing structure, response time commitments, and escalation procedures within a service agreement often reveal as much about a vendor’s reliability posture as their advertised uptime percentage. Similarly, the decision between timing belt replacement cost absorbed in-house versus outsourced to a managed service provider mirrors the broader DIY timing belt cost vs shop cost calculation: internal teams offer control and context, while specialist providers bring tooling and scale.
How Does Uptime Monitoring Help Manage Service Time and Downtime?
Uptime monitoring reduces service downtime by detecting failures faster than users do, enabling response before outages escalate — and providing the data needed to identify recurring failure patterns over time.
The core function of a monitoring tool is to continuously check whether a service is responding correctly and within acceptable performance parameters. When it detects an anomaly, it triggers an alert — by email, SMS, or webhook — that reaches the on-call team within seconds rather than minutes. This alone can cut MTTR significantly, because the most time-consuming part of incident response is often the time between a failure occurring and someone becoming aware of it.
Beyond alerting, monitoring platforms deliver several additional capabilities that directly support availability management:
- Status pages: Public-facing status pages keep users informed during outages, reducing inbound support volume and maintaining trust even when the service is unavailable.
- MTTR analytics: Dashboards that track Mean Time to Recovery over time help identify whether incident response is improving or degrading — and surface bottlenecks in resolution workflows.
- Outage history and trend analysis: Filtering and reviewing past incidents by type, duration, and affected component reveals systemic weaknesses that recurring patching or configuration changes have not yet resolved.
- SLA tracking: Automated SLA reporting removes the manual effort of compiling availability data for quarterly reviews and ensures that contractual commitments are being met or proactively flagged before they are breached.
What Advanced Metrics and Concepts Should You Know About Service Time and Downtime?
Beyond standard uptime percentages and SLA tiers, advanced practitioners rely on metrics like MTTR, MTBF, and the SLA/SLO/SLI framework to build a complete and honest picture of service reliability — one that reflects what users actually experience, not just what dashboards report.

These advanced concepts matter because the “nines” benchmarks, while useful for communication and contractual purposes, are lagging indicators. They tell you how reliable your service was last month. MTTR, MTBF, and the SLI/SLO/SLA hierarchy are leading and diagnostic indicators — they tell you where to invest effort before the next outage occurs, and whether your current reliability trajectory is improving or declining.
What Is the Difference Between MTTR and MTBF in Measuring Downtime?
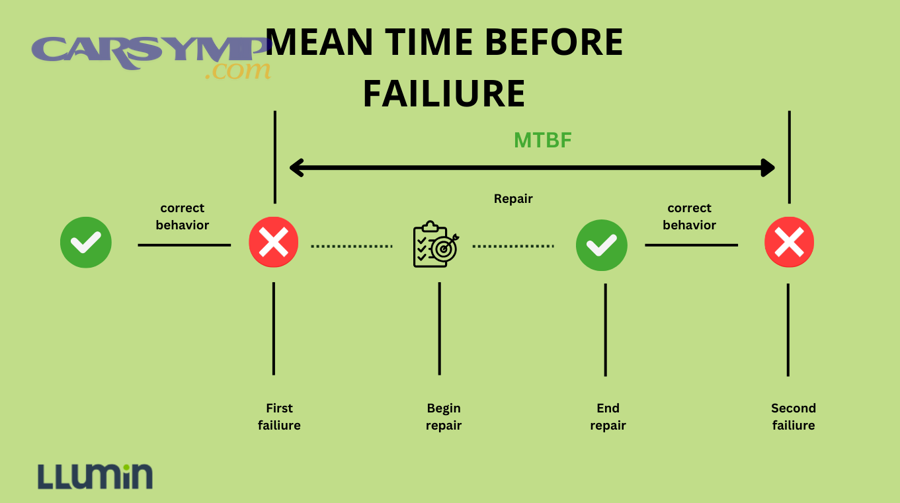
MTTR (Mean Time to Recovery) measures how quickly a service is restored after a failure, while MTBF (Mean Time Between Failures) measures how long a service typically runs before failing — making MTTR a measure of response efficiency and MTBF a measure of system reliability.
Both metrics feed directly into availability calculations. A system with a high MTBF fails rarely; a system with a low MTTR recovers quickly when it does fail. The ideal service has both — but in practice, improving MTTR often delivers faster ROI than improving MTBF, because reducing recovery time from 4 hours to 30 minutes dramatically improves the availability percentage without requiring any infrastructure investment. Conversely, a system that fails frequently but recovers in seconds may still achieve four-nines availability.
How each metric is calculated:
- MTBF = Total operational time ÷ Number of failures
- MTTR = Total downtime ÷ Number of incidents
For organizations making investment decisions about reliability, tracking both metrics together — rather than focusing exclusively on uptime percentage — reveals whether a reliability problem is rooted in failure frequency (an infrastructure or architecture issue) or recovery speed (an operational or tooling issue). The solution to each is fundamentally different.
What Is the Difference Between SLA, SLO, and SLI?
SLA, SLO, and SLI are three distinct but interdependent components of service reliability management: the SLA is the external contract, the SLO is the internal performance target, and the SLI is the actual measured metric that determines whether both are being met.
- SLA (Service Level Agreement): A formal, legally binding contract between a service provider and its customers defining the minimum acceptable service level. SLAs typically specify uptime percentages, response time commitments, and the penalties or remedies (such as service credits) that apply when those commitments are not met. They are external commitments with real commercial consequences.
- SLO (Service Level Objective): An internal performance goal set by the engineering or operations team, typically more stringent than the SLA. If an SLA promises 99.9% uptime, a well-run organization sets an internal SLO of 99.95% to create a buffer before the contractual threshold is breached. SLOs are management tools, not contracts.
- SLI (Service Level Indicator): The actual measurement — the raw data point that shows what the service delivered. Common SLIs include the percentage of successful HTTP requests, average response latency, and error rate. SLIs are fed into dashboards to determine whether SLOs and SLAs are being met in real time.
For organizations managing multiple workloads with different criticality levels, creating differentiated SLAs by tier — for example, a five-nines SLA for cloud infrastructure and a three-nines SLA for a development environment — ensures that reliability investments are proportional to business impact. Misaligning SLA, SLO, and SLI by failing to ensure the measured SLI corresponds to what the SLA actually commits to is one of the most common governance failures in enterprise IT service management.
What Is the “Watermelon Effect” in SLA and Uptime Reporting?
The watermelon effect describes a reporting condition where SLA metrics appear green on the outside — meaning the contractual uptime percentage has been met — while customer experience is red on the inside, meaning users are dissatisfied despite technical compliance.
This phenomenon arises when organizations rely exclusively on system-level uptime as their availability metric without correlating it with user-facing signals. A service can maintain 99.9% uptime while still delivering a poor experience if the 0.1% of downtime occurs consistently during peak usage hours, or if the service degrades in performance (slow response times, partial failures) in ways that don’t register as “downtime” under the SLA’s technical definition but are experienced as failures by users.
The watermelon effect is especially common when SLA reporting is handled by the same team responsible for meeting the SLA — creating an incentive to define and report metrics in the most favorable light. Addressing it requires adding user-centric SLIs (such as page load time, transaction success rate, and user-reported errors) alongside system-centric uptime metrics, and weighting SLO achievement against both. Tools that combine uptime monitoring with user satisfaction data — including CSAT scores and real-user monitoring (RUM) — provide the balanced visibility needed to detect watermelon reporting before it becomes a customer retention problem.
Does Downtime Apply Beyond IT Systems?
Yes, downtime applies meaningfully beyond IT systems — extending to human capital, manufacturing operations, and any environment where a productive asset is rendered temporarily non-functional.
In workforce management, the concept of “dead time” — employees unable to perform their work because a required system is unavailable — is a direct cost of IT downtime that rarely appears in standard availability reports. If a customer service team of 50 agents cannot access their CRM platform for two hours, the productivity loss is real and quantifiable, even though it doesn’t appear on a server uptime dashboard.
In manufacturing, downtime is a core concept within Total Productive Maintenance (TPM) — a methodology for measuring and improving the overall effectiveness of production equipment. Manufacturing downtime is categorized with similar precision to IT downtime: planned stops (scheduled maintenance, shift changes), unplanned stops (equipment breakdowns, quality defects), and speed losses (equipment running below optimal capacity). The parallel between manufacturing TPM and IT availability management is not coincidental — both disciplines evolved to answer the same fundamental question: how do you measure and maximize the useful output of a critical operational asset? For organizations managing both physical and digital infrastructure, applying a unified downtime framework across IT and operational technology (OT) systems is increasingly recognized as a best practice in enterprise reliability management.